Protein–Nucleic Acid co-folding and Specificity Prediction on Vecura
Getting a 3D model of a protein bound to DNA or RNA is usually called nucleic acid docking, and protein–DNA docking and protein–RNA docking are the phrases most people search for. Vecura does this through co-folding: a model takes the protein sequence and the nucleic acid sequence together and predicts the assembled complex in one step. A third operation on this page, protein–DNA specificity prediction, starts from a complex that already exists and answers a different question: not where the partners sit, but which nucleotide sequences the protein prefers.
For nucleic acids in particular, co-folding is the stronger method, and the reason is specific. Classical docking holds both partners rigid and searches for the best way to place them against each other, which assumes each one already has the shape it will take once bound. Nucleic acids break that assumption harder than almost anything else: DNA bends and kinks sharply around the proteins that read it, and RNA routinely refolds on binding. Co-folding makes no such assumption. It predicts the conformation of each chain and the interface between them at the same time, so induced fit is part of the prediction rather than an error the scoring function has to absorb, and the models doing it learned recognition from experimental complexes rather than from a generic energy term.
What co-folding needs, and what it gives back
| Co-folding | Classical docking | |
| Input | Two sequences | Two 3D structures (PDB) |
| What the model decides | The conformation of each chain and the interface between them, together | Only the relative placement; each partner's shape is taken as given |
| Induced fit | Predicted as part of the complex | Not modelled, the input conformations are what you get |
| Output | One predicted complex with confidence metrics | Ranked alternative poses with scores |
The one thing to settle before you start is your input. Co-folding runs from sequence, so if your starting material is a pair of experimental structures you will be supplying their sequences and letting the model rebuild the complex rather than posing the structures themselves. For most protein–nucleic acid work that is the right trade, the bound conformation is usually not the one in your unbound structures anyway, but it is worth knowing in advance rather than discovering mid-run.
Choosing an operation
| What you have | What you want | Use |
| Protein sequence + DNA sequence | A predicted protein–DNA complex | Protein–DNA co-folding |
| Protein sequence + RNA sequence | A predicted protein–RNA complex | Protein–RNA co-folding |
| Protein–DNA complex structure | Per-position nucleotide preferences | Protein–DNA specificity prediction |
Protein–DNA co-folding
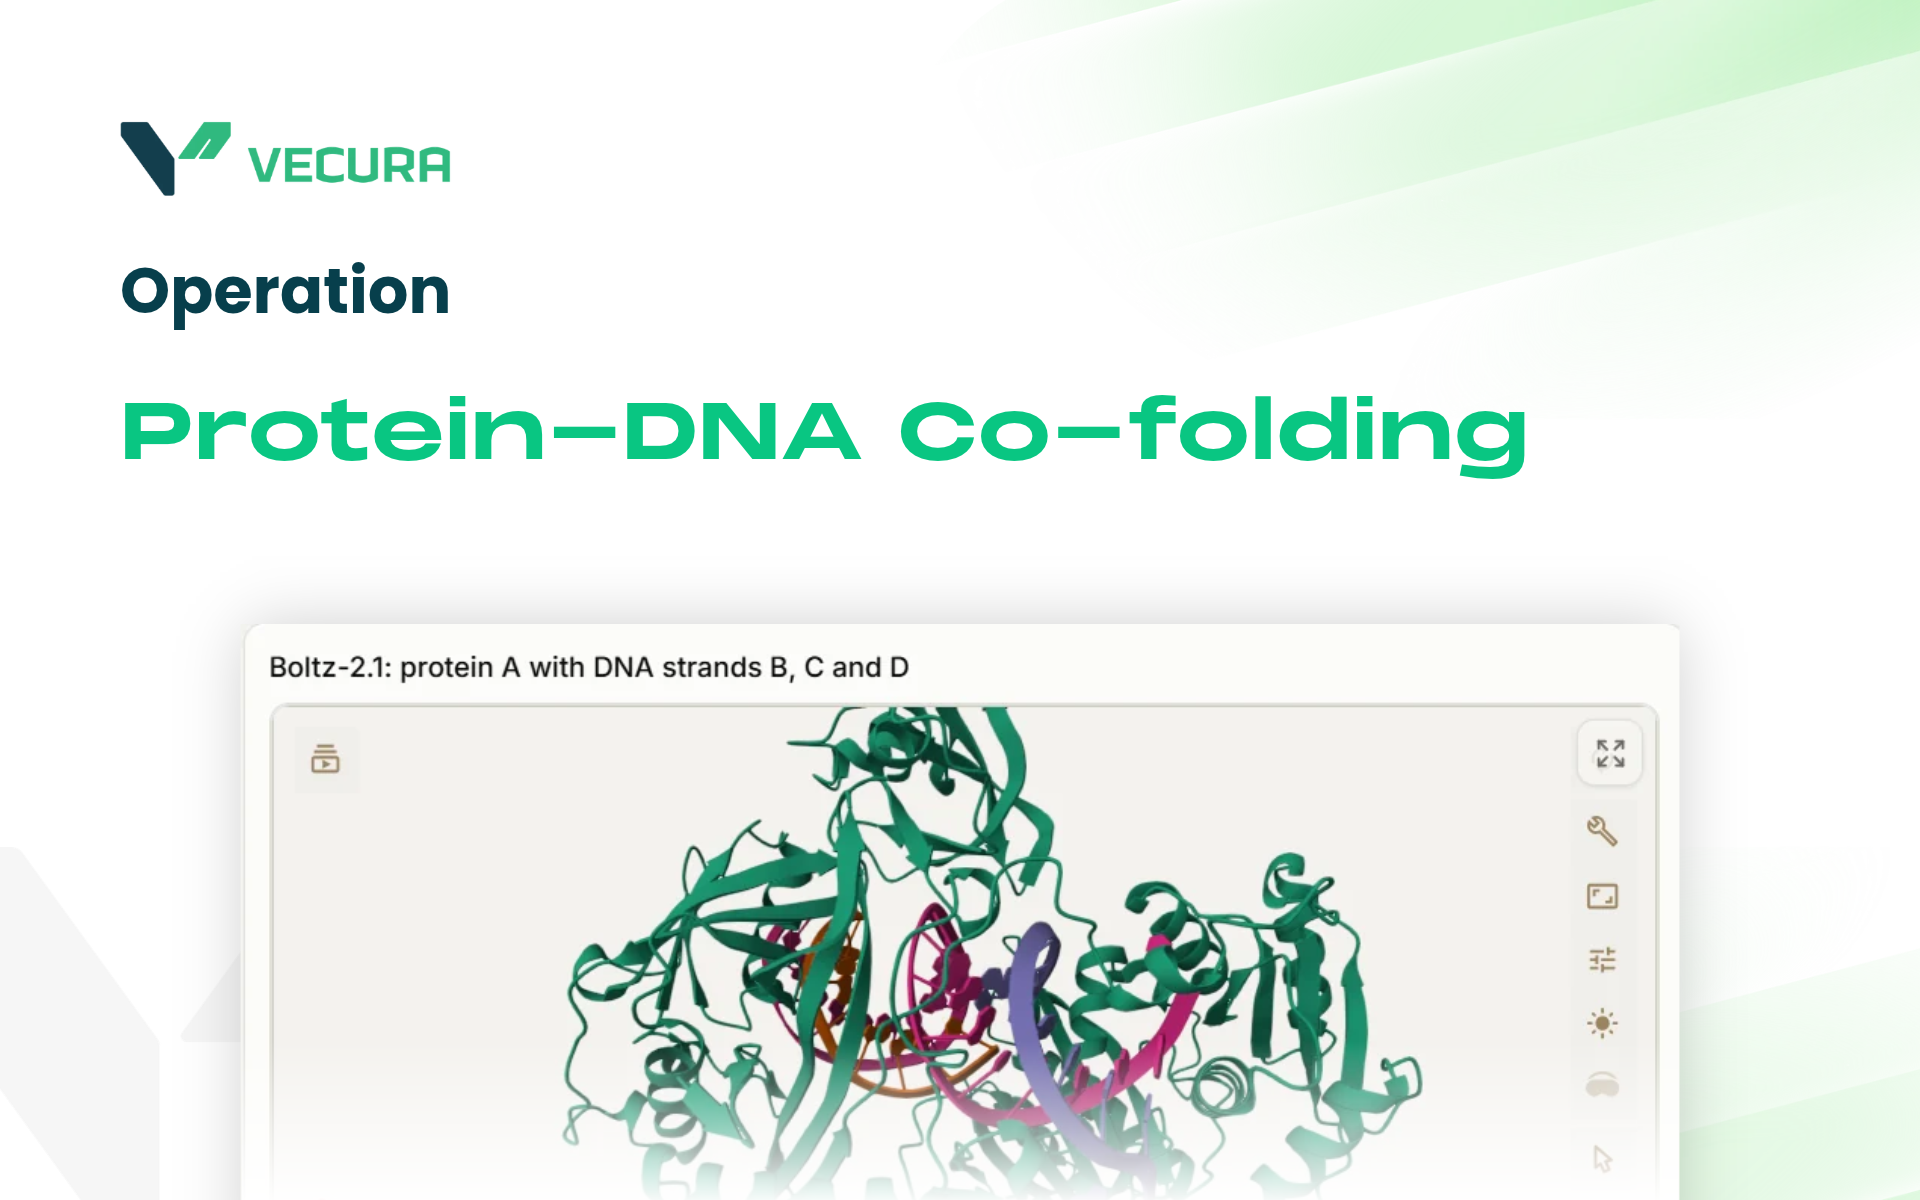 ユースケースのリプレイProtein-RNA Co-foldingこのユースケースを見る
Predicts the structure of a protein bound to a DNA partner from the two sequences. This is the operation to use if you came looking for protein–DNA docking: same deliverable, different input.
Use it when you need a structural model of a protein–DNA interaction and do not already have one, a transcription factor on its recognition site, a repair enzyme on damaged DNA, a nuclease on its substrate. It answers where the partners sit. Once you have that complex, specificity prediction answers which sequences the protein actually prefers there.
入力
Protein sequence; DNA sequence (ATCG)
出力
Predicted protein–DNA complex structure
Which model
Seven models predict protein–nucleic acid complexes. They divide by how you hand them the partners, and that is the practical basis for choosing:
| Model | How partners are supplied | Operation |
| Boltz-2.1 | One assembly field — protein, DNA, RNA, or ligand (SMILES or CCD) | generate_biomolecule_structure |
| Protenix | One assembly field — each row becomes one chain, in order | generate_biomolecule_structure |
| OpenDDE | One assembly field — chain IDs assigned automatically | generate_biomolecule_structure |
| OpenFold3 | One assembly field — chain IDs assigned automatically | predict_structure |
| Chai-1 | Separate fields: protein (required), dna (ATCG), rna (AUGC) | generate_biomolecule_structure |
| IntelliFold | Separate fields: protein, dna (ATGC), rna (AUGC), both optional | generate_biomolecule_structure |
Reach for Chai-1 or IntelliFold when the assembly is one protein plus one nucleic acid, the separate fields make that explicit and hard to get wrong. Reach for the assembly-style models when the complex is larger or mixed: several chains, or a nucleic acid together with a ligand, where you need control over what goes in and in what order. Note that OpenFold3 exposes this under predict_structure rather than generate_biomolecule_structure, which matters if you are chaining operations by name.
Protein–RNA co-folding
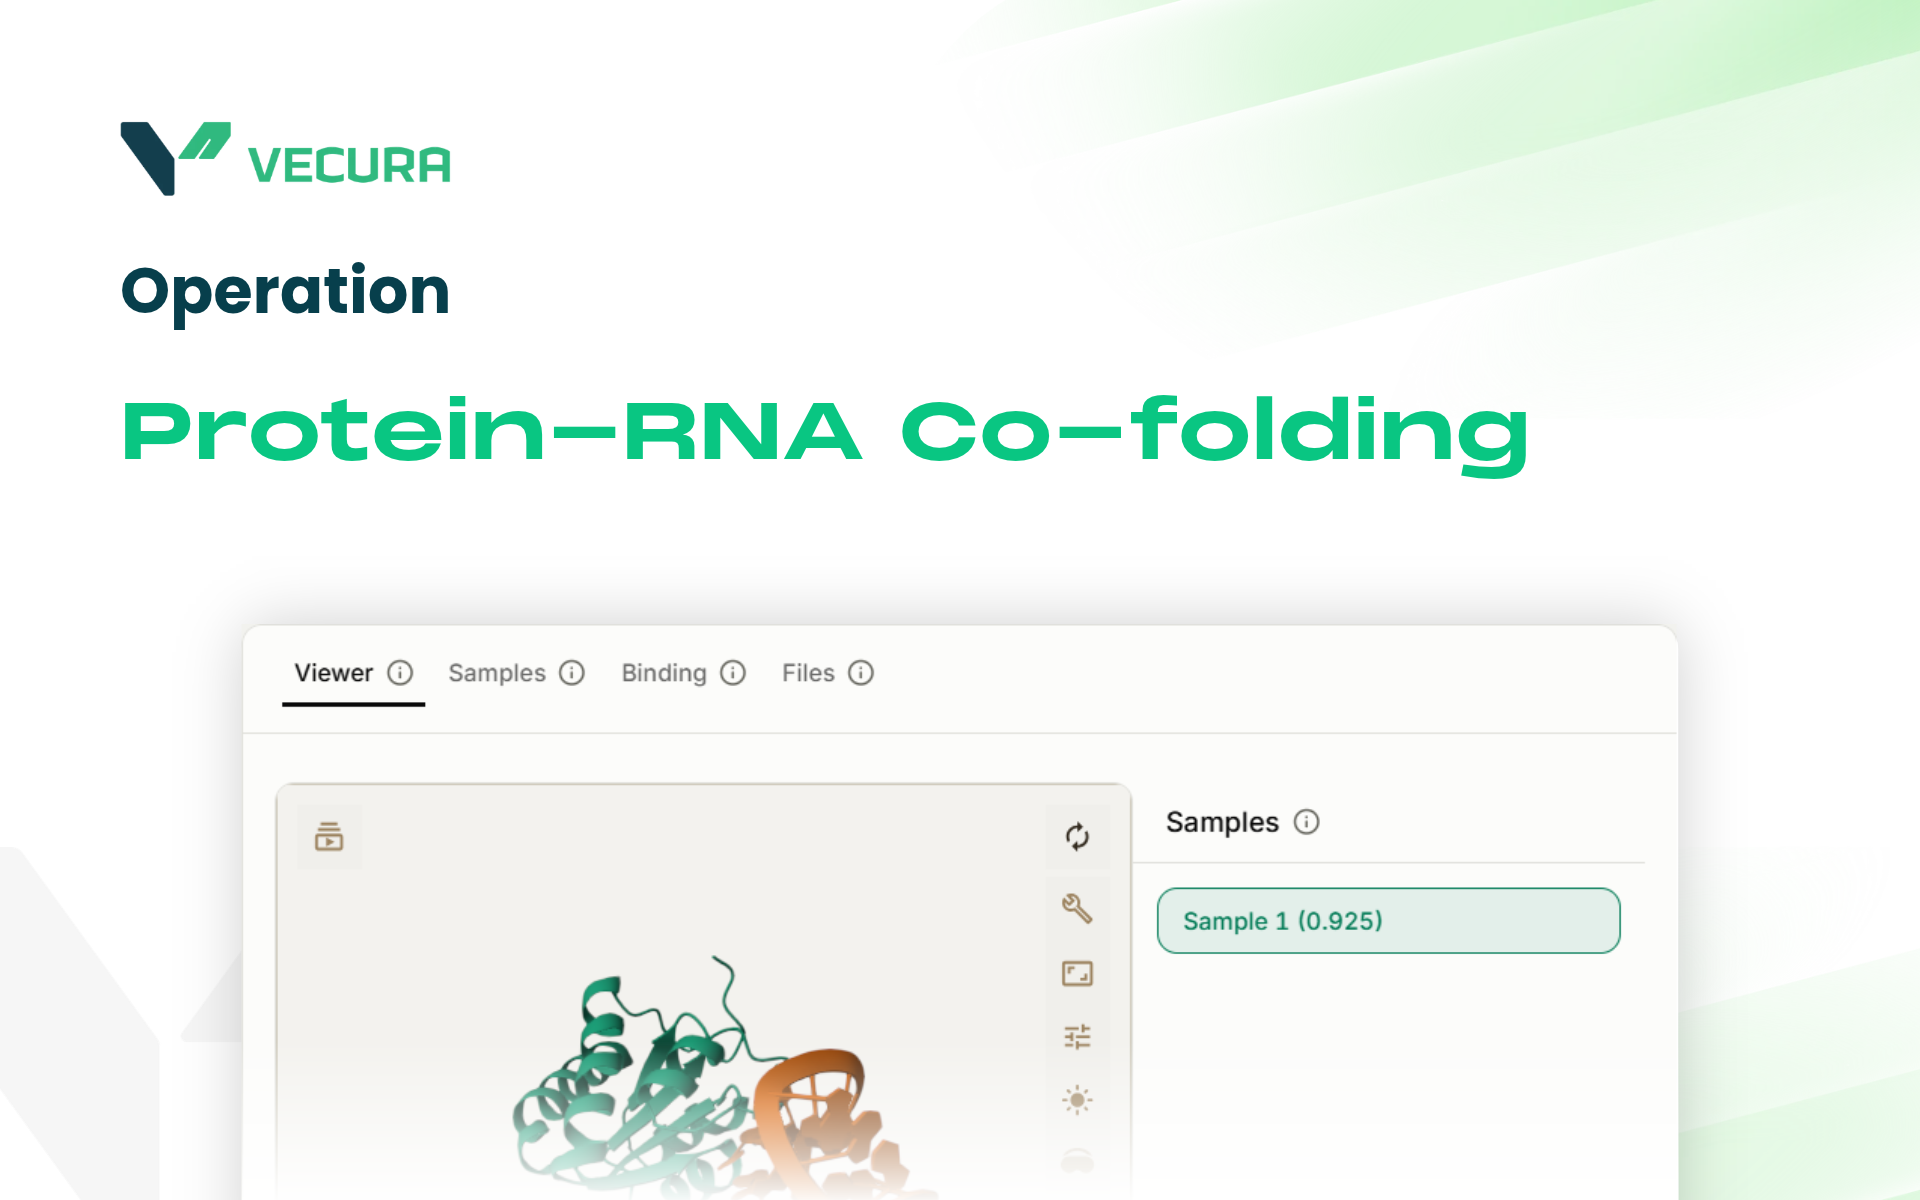 ユースケースのリプレイProtein-RNA Co-foldingこのユースケースを見る
Predicts the structure of a protein bound to an RNA partner — the route for anyone searching protein–RNA docking.
A DNA duplex is close to a regular B-form helix, so the model has comparatively little to decide about the partner's own shape. An RNA partner has a tertiary fold that the model is predicting at the same time as the interface, which means the fold itself is part of what you are trusting. Treat an RNA complex with more scepticism than a DNA one at the same confidence score, and check the RNA fold against anything you know about it independently.
入力
Protein sequence; RNA sequence (AUGC)
出力
Predicted protein–RNA complex structure
Which model
The same seven models, chosen on the same basis as for protein–DNA co-folding above. Where the RNA chain goes:
| Model | RNA input |
| AlphaFold3, Boltz-2.1, Protenix, OpenDDE, OpenFold3 | Add an RNA chain to the assembly field |
| Chai-1 | rna field, AUGC |
| IntelliFold | rna field, AUGC, optional |
RNAPro is not among them despite being an RNA structure model: it takes RNA sequences only, with no protein input, so it predicts RNA structure alone rather than protein–RNA complexes.
Protein–DNA specificity prediction
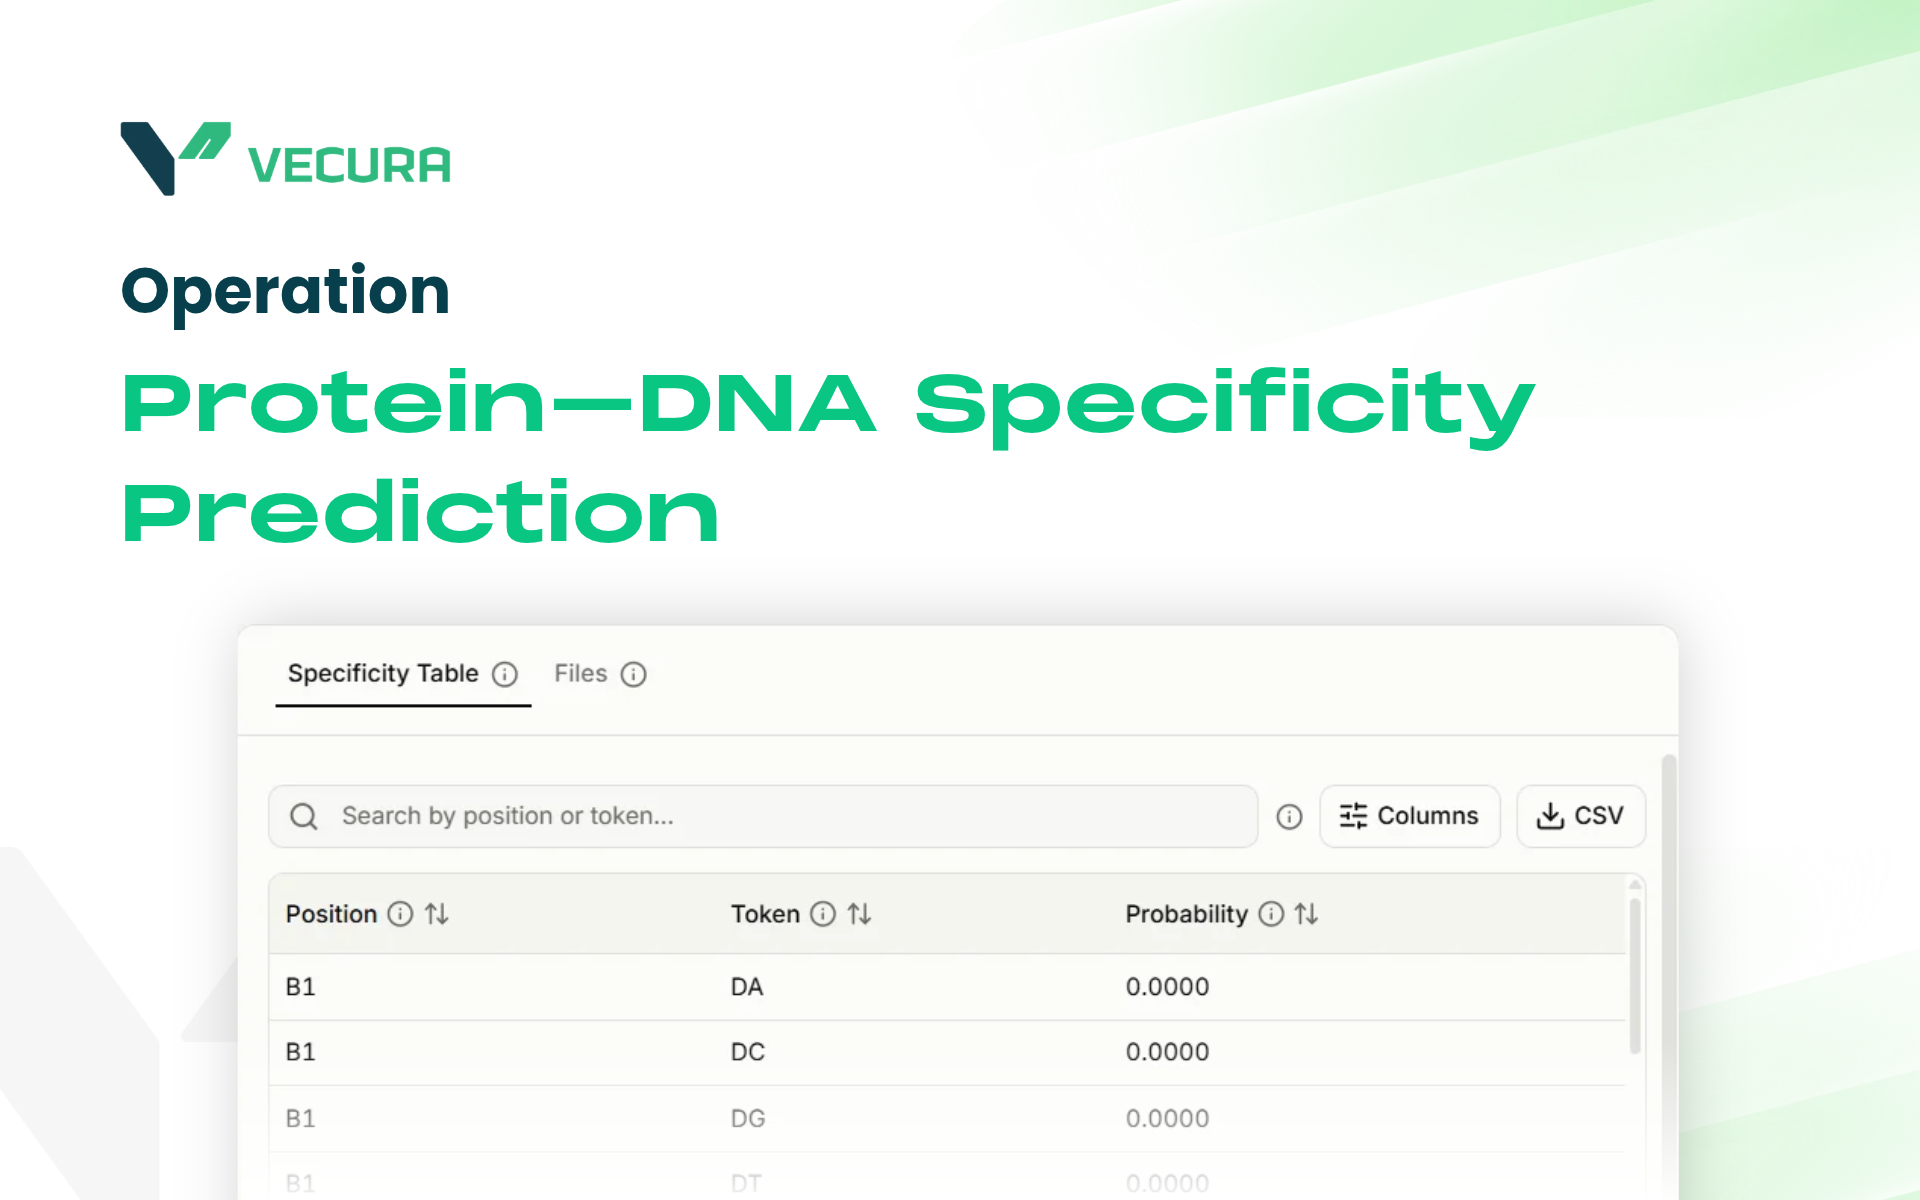 ユースケースのリプレイProtein-DNA Specificity Predictionこのユースケースを見る
Predicts which DNA bases a protein prefers at each position of a bound nucleic acid, given the complex structure. This is also what "binding specificity prediction" refers to on the platform — one operation, taking one complex PDB, not two separate capabilities.
Use it when the geometry is settled and the open question is recognition: which bases are read out, and how tolerant each position is. It does not produce or refine a structure. If the complex you feed it came from co-folding rather than experiment, the prediction inherits whatever error is in that structure, which is worth stating in any result built that way.
入力
Protein–DNA complex structure (PDB)
出力
Per-position nucleotide preferences
Which model
NA-MPNN (Baker Lab) is the only model exposing this operation, so there is no neighbour to choose against. It is a message-passing neural network for backbone-conditioned nucleic acid sequence design and protein–DNA binding specificity prediction. Given a complex structure it auto-detects the chains present and returns predicted sequence preferences conditioned on that fixed geometry. It scores preference from structural context — it does not compute binding free energy and is not a substitute for physics-based simulation. When a protein chain is present its sequence is held fixed; NA-MPNN designs the nucleic acid, not the protein.
Next step
A co-folded complex is a prediction, not a measurement, so the natural next group is Molecular Dynamics / Trajectory / Ensemble Analysis: running a short simulation on the predicted complex shows whether the interface holds together or comes apart, which is the cheapest available check on whether the structure is worth building further work on. For a complex you intend to design against rather than just inspect, that stability check belongs before any downstream design step.