ReverseLigQ: Streamlining Ligand-Driven Target Discovery on Vecura
This update allows researchers and medicinal chemists to rapidly identify potential protein targets for small molecules through an intuitive, guided workflow on Vecura, eliminating the need for complex local infrastructure.
What is ReverseLigQ?
ReverseLigQ is a specialized tool for ligand-driven protein target discovery that reverses the traditional drug-discovery workflow. Instead of screening compounds against a known protein, it starts with a query small molecule (SMILES) and identifies potential protein targets within a selected organism. By utilizing chemical similarity metrics and mapping ligands to Pfam binding domains, the model predicts which proteins are most likely to interact with a specific chemical scaffold.
It helps researchers rapidly identify protein candidates without requiring computationally expensive structural docking or prior binding-affinity data. It is especially useful for target identification during early-stage drug discovery or for investigating the potential mechanisms of action for natural products and novel compounds.
What can users do with ReverseLigQ on Vecura?
With ReverseLigQ on Vecura, users can:
- Input a chemical structure as a SMILES string to identify candidate protein targets.
- Select from thirteen supported organisms, including human pathogens like M. tuberculosis and SARS-CoV-2, as well as Homo sapiens.
- Choose between two similarity search algorithms: high-speed Morgan fingerprint/Tanimoto similarity or transformer-based ChemBERTa embeddings for structurally diverse matches.
- Refine results by toggling between "curated" (experimentally confirmed) and "possible" binding-domain evidence to prioritize candidates for experimental validation.
What the output means
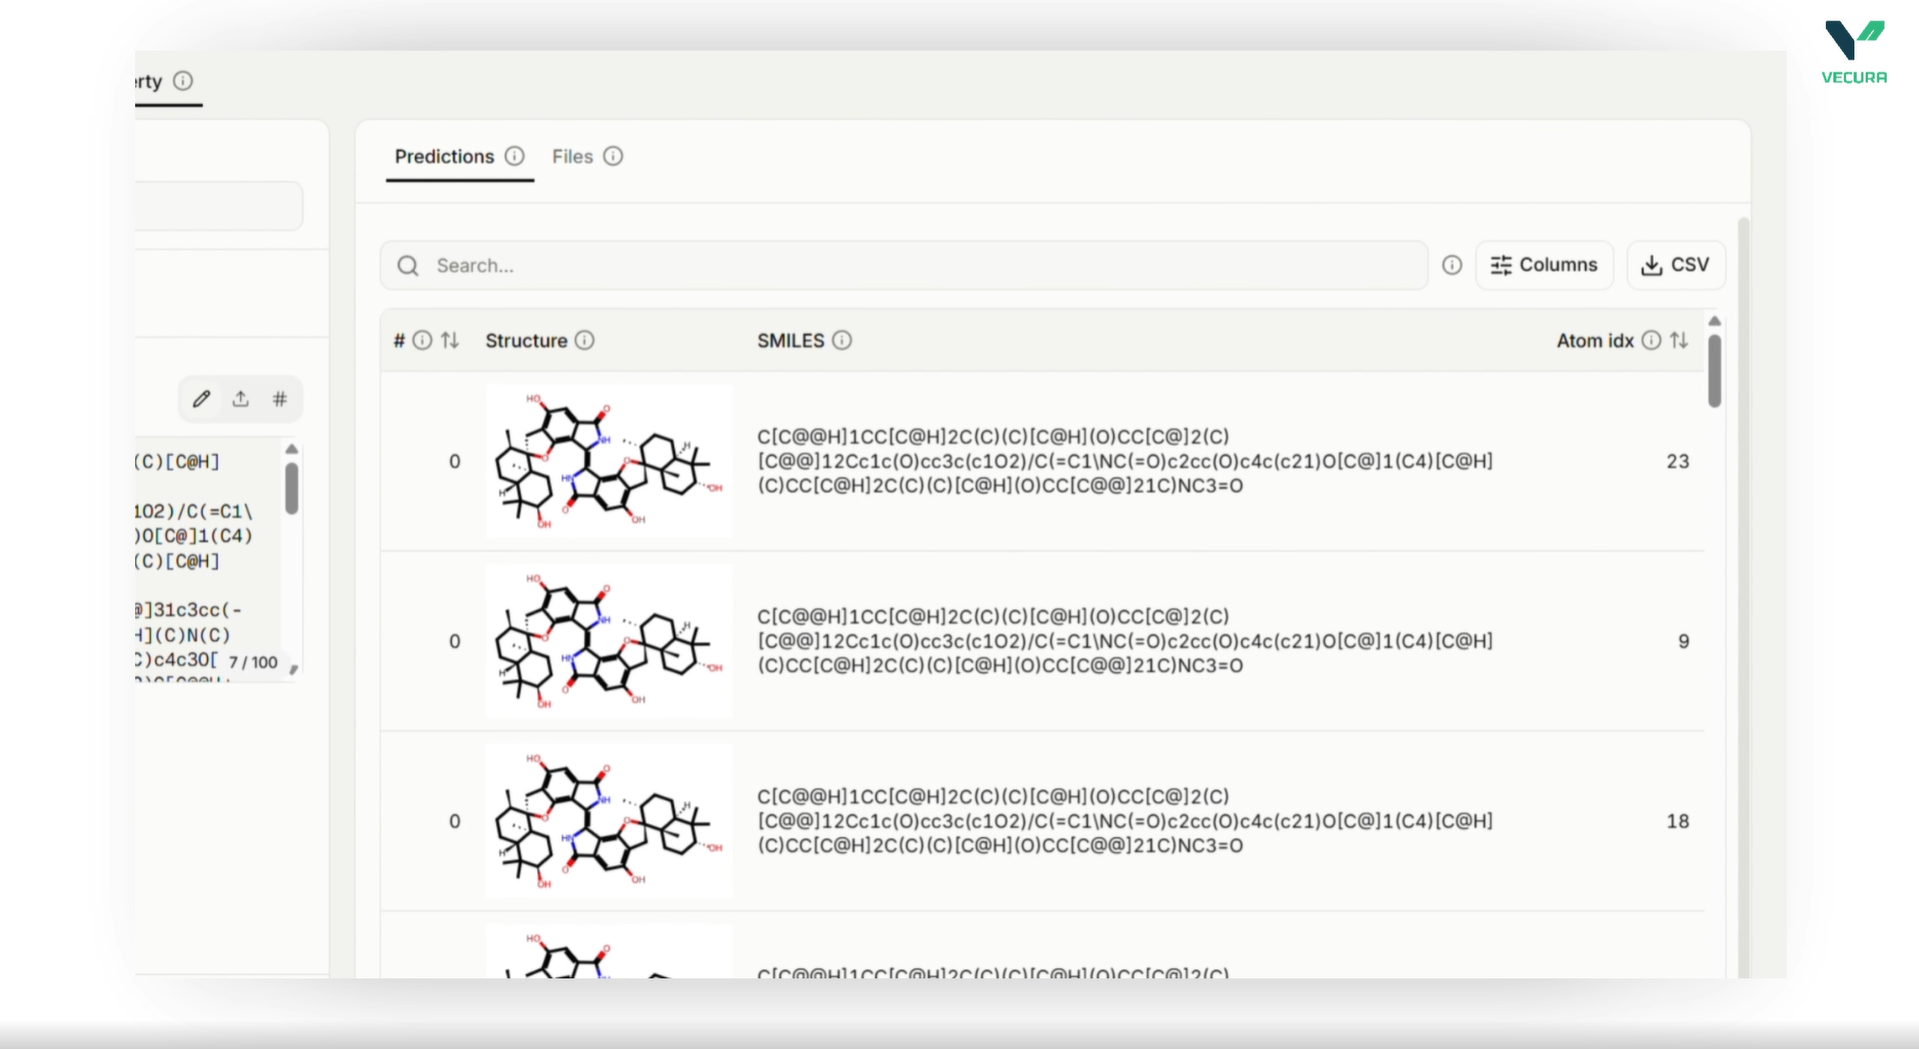
The output provides a ranked list of candidate protein targets mapped to their respective Pfam binding domains. Each entry is supported by evidence derived from chemically similar reference ligands, complete with the specific ligand used for the prediction and a similarity score.
This output should be used to support scientific decision making by generating hypotheses for further research. It does not replace experimental validation and should be interpreted as a guide for laboratory prioritization.
Why this matters
The challenge of identifying the biological targets of small molecules is a significant bottleneck in therapeutic development. Traditional methods often require extensive, time-consuming experimental setups or complex structural simulations. By providing a streamlined, ligand-driven approach, ReverseLigQ allows researchers to bridge the gap between chemical structures and potential biological functions much earlier in the discovery pipeline.
This capability is particularly valuable for drug repurposing and understanding the off-target profiles of lead compounds. It enables a more efficient allocation of resources by allowing scientists to focus their experimental efforts on the most likely protein-ligand interactions.
- Developed by: G. Schottlender
- Source: ReverseLigQ GitHub Repository
- Reference: https://github.com/gschottlender/ReverseLigQ
在 Vecura 上试用 ReverseLigQ
打开模型工作区,用您自己的输入开始评估